MIT AI Teaches Robots to Read Between the Lines
MIT researchers built an AI framework that connects language models to robotic actuators, letting machines infer unstated rules and navigate complex spaces.
MIT CSAIL researchers have developed a hybrid AI framework that couples large language models directly to robotic control pipelines, enabling autonomous machines to execute vague human commands without pre-scripted trajectory maps. Unveiled in research co-authored by MIT Assistant Professor Andreea Bobu, PhD student Alexandra Forsey-Smerek, and postdoc Nathaniel Dennler, the system allows physical agents to infer implicit spatial constraints directly from conversational context. Rather than requiring robotics engineers to manually code every environmental boundary, the platform uses language model reasoning to parse broad instructions into real-time safety parameters. In laboratory demonstrations, robots given vague prompts successfully inferred unstated physical rules, such as automatically keeping safe clearance around all delicate electronic equipment when asked to avoid a single laptop.
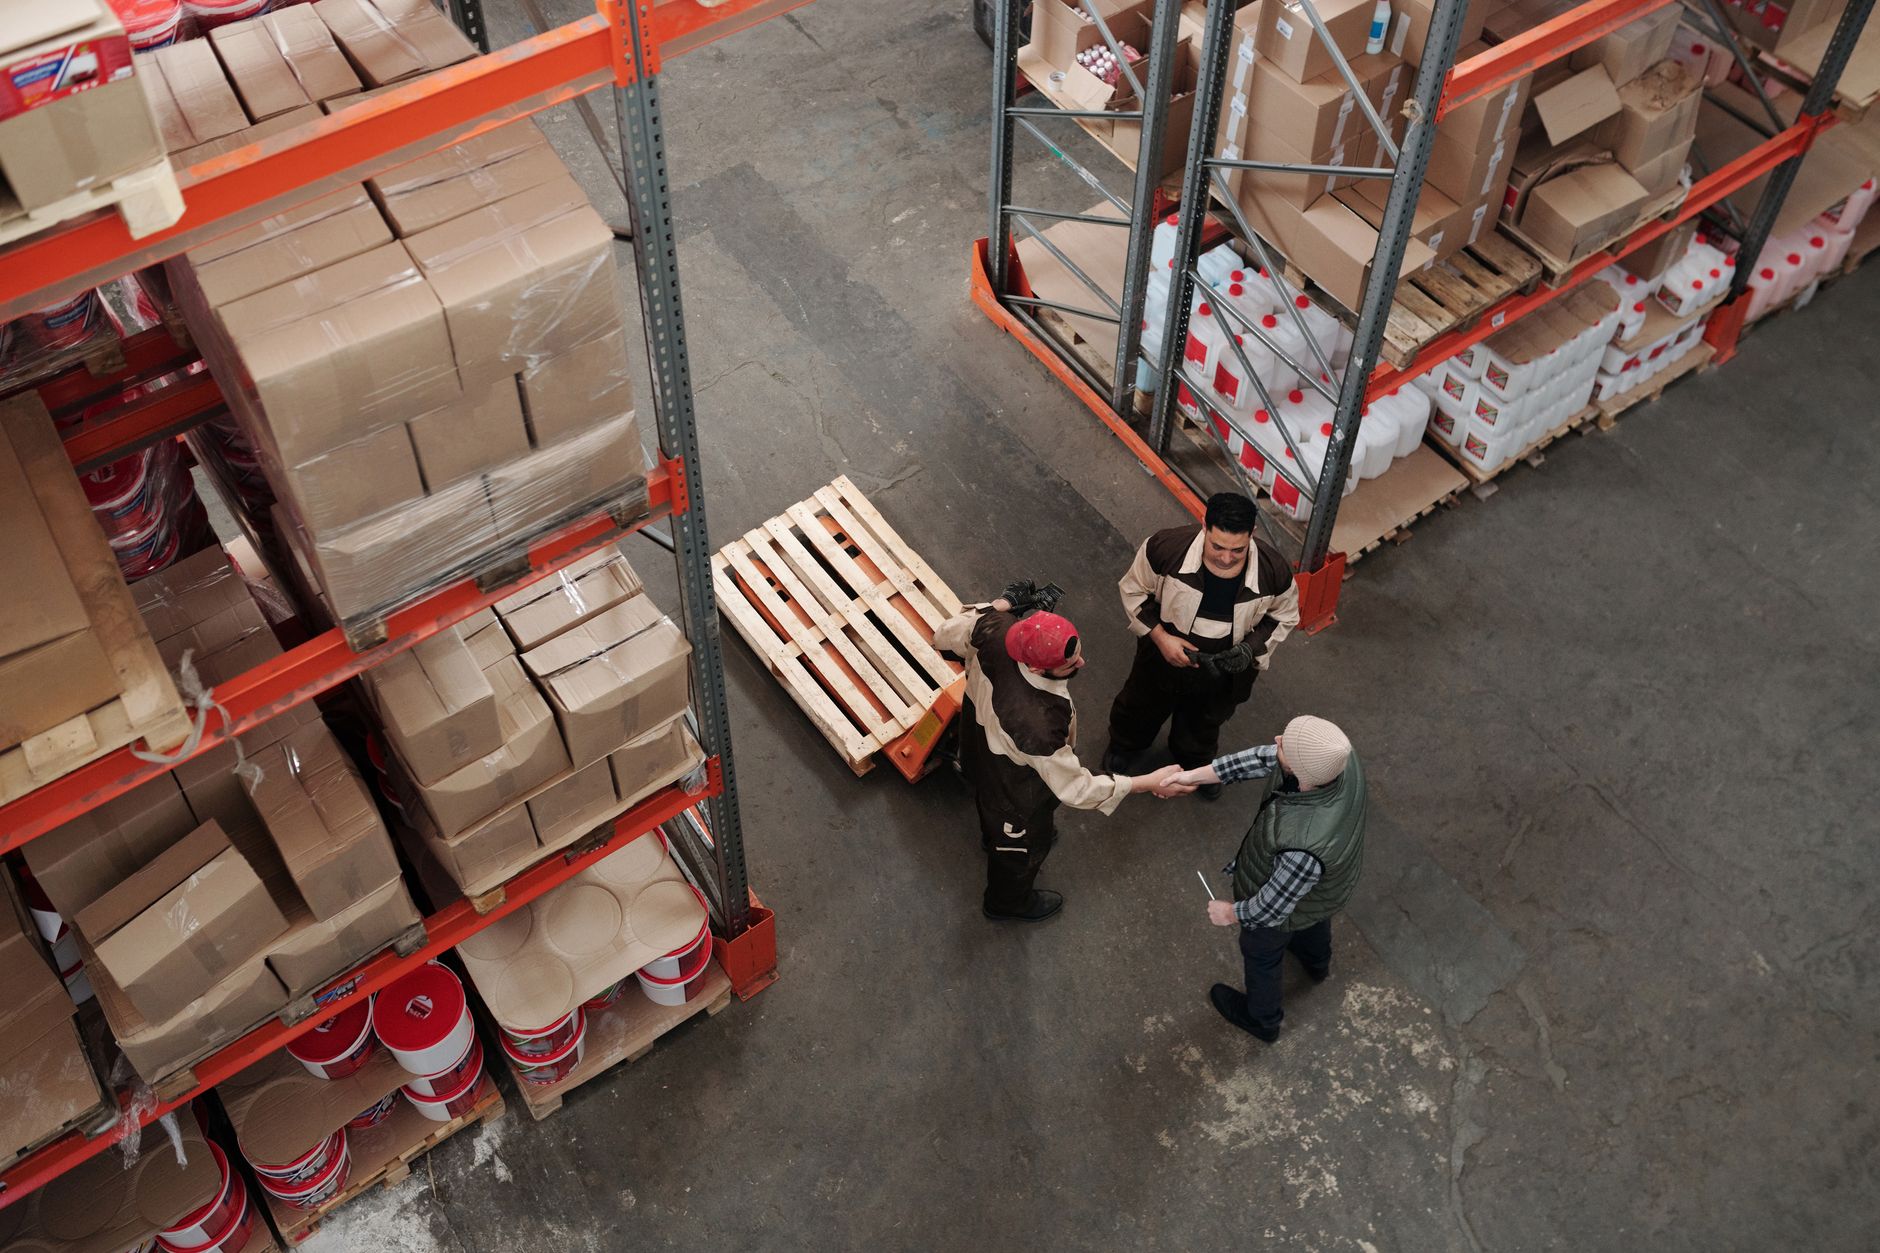
Industrial robotics deployments have historically hit a commercial wall due to the immense software overhead of deterministic path planning. In unstructured real-world environments like healthcare facilities, dynamic warehouses, and commercial kitchens, minor spatial shifts historically required software engineers to manually rewrite control scripts and recalibrate vision systems. While large language models have transformed digital productivity, linking high-level natural language reasoning with physical actuators has remained a critical engineering bottleneck. The MIT team solves this systemic disconnect by embedding spatial reasoning hierarchies into low-level motor controllers, converting contextual intent into exact motion primitives without human intervention.
Supported in part by the Tata Group through the MIT Generative AI Impact Consortium Award and the U.S. Department of Defense, the research demonstrates how multi-modal vision systems improve when agents filter out non-essential visual data. Findings detailed by MIT News reveal that using language models to guide inverse reinforcement learning dramatically reduces manual trajectory engineering in unscripted workplace settings. The underlying architecture builds on multi-agent evaluation techniques similar to those tested on KramaBench, an MIT benchmark analyzing complex pipeline decisions across dynamic datasets. By combining intent recognition with tree-search reasoning methods, the platform ensures that robots prioritize vital physical obstacles while filtering out irrelevant background noise.
For venture capitalists and hardware founders, this technical breakthrough alters the fundamental unit economics of autonomous robotics deployment. By eliminating the necessity for extensive facility mapping, custom sensor calibration, and rigid environment structuring, deployment timelines for industrial automation can drop from months to hours. Early-stage startups building autonomous mobile robots, automated sorting systems, and collaborative workplace assistants gain an immediate strategic edge in customer acquisition. Systems capable of understanding human nuance will unlock entirely new customer segments across mid-market logistics, agricultural packing, and specialized facilities management where rigid scripting was previously cost-prohibitive.
Over the next 12 months, commercial robotics manufacturers will begin shifting contextual language models directly onto low-power embedded processors at the hardware edge. Moving semantic reasoning off cloud servers and onto local silicon will drastically reduce control latency while maintaining essential operational privacy. Initial pilot deployments across enterprise warehouse fleets will test whether these contextual reasoning architectures can sustain strict zero-collision benchmarks during continuous multi-shift operations. As physical foundation models mature, the boundary separating digital language understanding from real-world robotic manipulation will dissolve, paving the way for adaptable general-purpose autonomous fleets.
 The Future FrontBe on the cover.Twice a month we put the people shaping what's next on our cover.Apply for the cover